SQL vs NoSQL: How to Choose
SQL vs NoSQL explained: data models, consistency, scaling, query flexibility and when to use relational, document, key-value, wide-column or graph databases.
How B-tree and LSM-tree storage engines work, why one favours reads and the other writes, write and read amplification, compaction and which databases use each.
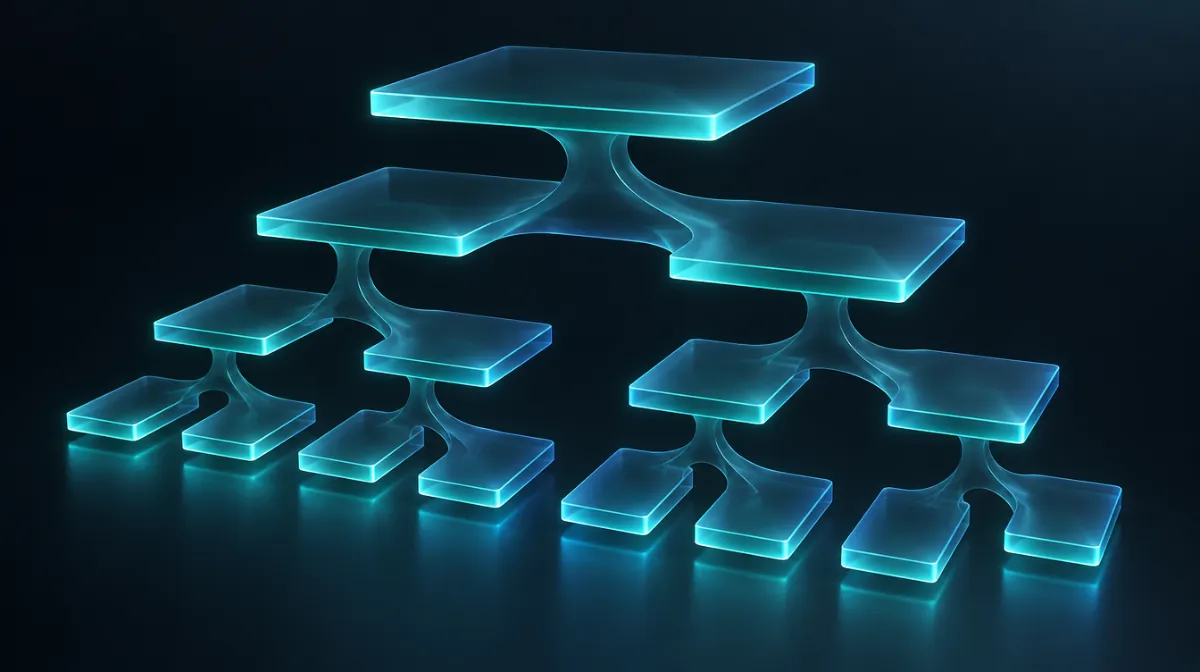
Underneath every database is a storage engine that decides how data is laid out on disk. The two dominant designs, B-trees and log-structured merge trees (LSM trees), make opposite trade-offs, and knowing them helps you pick the right database for a workload.
A B-tree keeps keys sorted in fixed-size pages arranged in a shallow, balanced tree. Finding a key means walking from the root to a leaf, usually just a few page reads, even for huge tables.
Writes update pages in place. To survive crashes, changes are first recorded in a write-ahead log. When a page fills up, it splits.
Strengths: fast, predictable reads and range scans; mature and well understood. Most relational databases use B-tree indexes; our guide to database indexing shows how to design them for your queries.
An LSM tree turns random writes into sequential ones:
Reads check the memtable, then files from newest to oldest. Bloom filters let the engine skip files that definitely don’t contain a key.
Strengths: very high write throughput and good compression. Many wide-column and key-value stores use LSM trees.
| B-tree | LSM tree | |
|---|---|---|
| Write pattern | Random, in place | Sequential, batched |
| Write throughput | Good | Excellent |
| Read latency | Predictable | Can vary; more files to check |
| Write amplification | Page rewrites | Compaction rewrites |
| Space | Some fragmentation | Better compression; temporary duplicates |
| Background work | Little | Compaction needs I/O headroom |
Every engine balances these three; tuning compaction strategy shifts the balance for LSM trees.
Engine choice often comes bundled with your database choice; see SQL vs NoSQL. At larger scale, combine it with sharding.
Because files are immutable, updates and deletes create new entries. Compaction merges files and removes obsolete data to keep reads and storage efficient.
Not slow, but random in-place updates are generally less efficient than sequential batched writes.
A compact probabilistic structure that can say “definitely not here” or “possibly here”, letting LSM engines skip unnecessary file reads.
Every article is edited by a human and checked against our editorial policy. Spotted a mistake? Tell us.
SQL vs NoSQL explained: data models, consistency, scaling, query flexibility and when to use relational, document, key-value, wide-column or graph databases.
What database sharding is, when you need it, how to choose a shard key, range vs hash vs directory sharding, and the operational pain points to plan for.
How database indexes work: B-tree and other types, composite and covering indexes, why queries ignore indexes, the write cost and checking with EXPLAIN.